Mindscape Explorer
Browse charts immediately once loaded; search results refine as passages are scored.
I’ve listened to Sean Carroll’s Mindscape podcast for years and wanted to explore questions that extend across episodes. The Explorer brings eight years of transcripts together so you can search for a discussion, find related episodes, or examine how the show’s subjects change over time. Search returns passages with timestamps and can play the episode from that moment. Recommend compares episodes by their topics, including connections through less prominent themes. Explore contains the maps, topics, guests, and timeline; each detailed topic lists the episodes and the specific moments where it comes up unexpectedly, and its words link to a search of the rest of the archive. Findings explains the analyses. The build log describes how I put these parts together.
In a businessTeams often hold thousands of documents without knowing which topics matter yet. This project turns a large text collection into searchable passages and topic views, so someone can find relevant material and sharpen their question.
Technical skills: Python · scikit-learn · sentence-transformers · Topic modeling · UMAP · Data visualization
- My contribution
- I set the specifications around questions I had about the archive and built the Explorer. I compared word-based topics with embeddings to check how much the findings depend on the representation.
- Result and limit
- The Explorer makes 441 episodes and roughly 7.4 million words browsable through search and topic views. Its analysis includes transcripts through 2026-09-21.
On this page
The Explorer’s analysis covers 441 episodes through 2026-09-21. Search uses the current 441-episode index through 2026-09-21.
What an episode can lead to
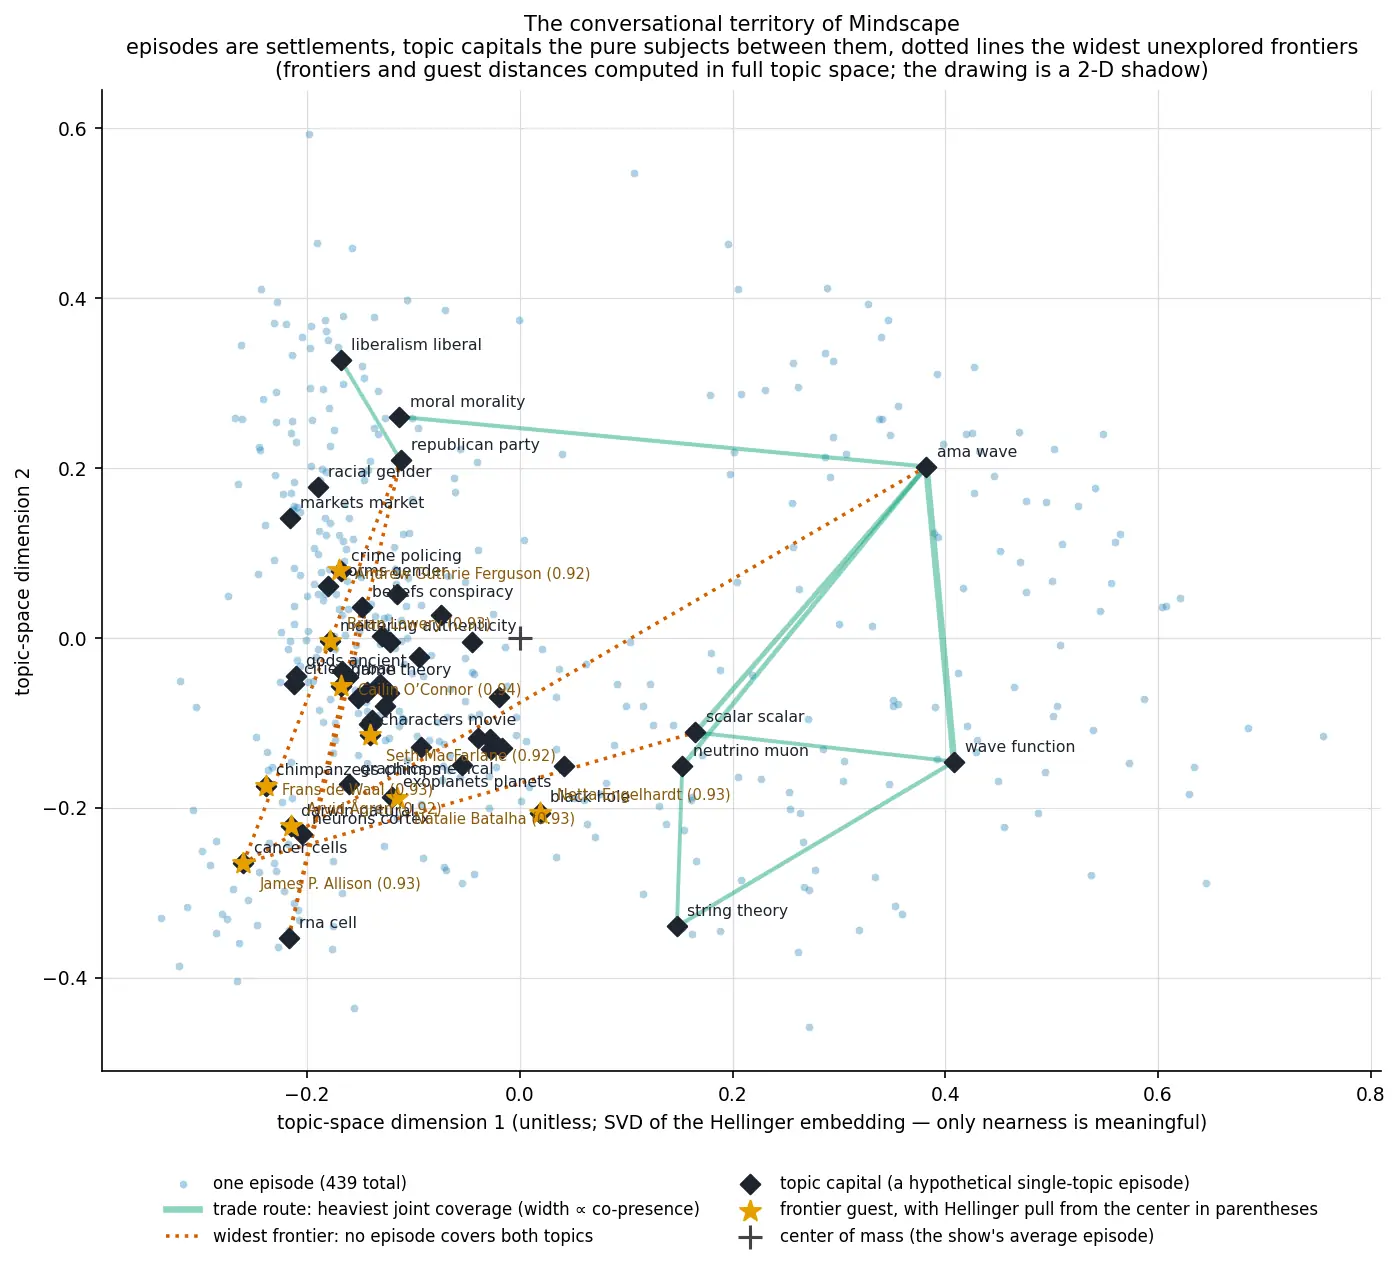
Pick an episode in Recommend (opens in a new tab) to see familiar territory, unexpected connections, and episodes with the least topical overlap. The serendipity list had greater diversity than the similar-episode list, while measured novelty was nearly unchanged. These are corpus-based measures, not listener ratings.
Technical methods and evaluation
The tables and measurements below record the earlier 439-episode analysis, which selected 50 topics at the middle resolution (27 and 92 at the others). The September refresh reran the full pipeline on 441 episodes; the same selection rule now picks 40 (22 and 74). Current charts and results are available in the live Explorer’s Findings view (opens in a new tab).
Jump to topic evaluation, recommendations, or search.
Corpus
| Measure | Value |
|---|---|
| Posts fetched from the WordPress API | 444 |
| Episodes with a transcript | 439 |
| Transcripts parsed into labeled utterances | 436 (3 were published without speaker labels and carry a flag) |
| Transcript words | 7.39 million |
| Date range | July 2018 to September 2026 |
| Requests to the site per full run | 20 to 30, three seconds apart, every response cached |
Topic model
I give more weight to terms that distinguish an episode from the rest of the archive (TF-IDF), then group recurring patterns into topics using nonnegative matrix factorization (NMF). Terms can contain one to three words. The number of topics is swept and selected by the one-standard-error rule on a combined coherence-and-stability score, which gives an anchor of 50; the two other resolutions are 27 and 92, the anchor divided and multiplied by τ ≈ 1.839. Nesting between resolutions is inspected with a similarity matrix and a best-parent table rather than assumed.
Check against the host’s own tags
The topics were fit without seeing Sean’s hand-assigned subject tags. One classifier per tag, tuned on inner folds and scored by nested cross-validation, 17 tags, format tags excluded.
Reading the scores. Macro AP (average precision) measures how well episodes with each tag rise to the top of a ranked list, averaged equally across the 17 tags. ROC-AUC measures how well tagged episodes rank above untagged ones: 0.5 is chance and 1 is perfect separation. Higher is better for both.
| Features | Model | Macro AP | ROC-AUC |
|---|---|---|---|
| Topic loadings, three resolutions concatenated | Gradient boosting | 0.649 | 0.913 |
| Full TF-IDF matrix (baseline) | Logistic regression | 0.549 | 0.848 |
| Chance | 0.078 | 0.500 |
The classifier performs well on Physics (0.90), Biology (0.89), Astronomy (0.88), Economics (0.84), and Environment (0.81). Humanity (0.42), World (0.38), and Psychology (0.37) are harder to predict. This may reflect differences in how those categories are assigned, although classifier performance alone cannot establish the explanation.
Recommender
Relevance is topical affinity (the Bhattacharyya coefficient between topic distributions, averaged over the three resolutions). Metrics follow Kaminskas and Bridge (2016); intervals are 95% percentile bootstraps over 439 seed episodes, 2,000 resamples. Coverage and Gini are census quantities and carry no interval.
Reading the table. Diversity measures how different the recommendations are from one another. Coverage is the share of the archive recommended at least once across the tested starting episodes. Gini measures how unevenly recommendations are distributed across episodes: higher values mean a few episodes dominate.
| List | Intra-list diversity | Novelty | Catalogue coverage | Gini |
|---|---|---|---|---|
| More like this | 0.49 (0.48–0.50) | 0.64 (0.63–0.65) | 99.5% | 0.23 |
| Serendipity | 0.82 (0.81–0.82) | 0.64 (0.64–0.65) | 99.8% | 0.31 |
| Least likely from here | 1.00 | 0.82 (0.82–0.82) | 36.7% | 0.91 |
Serendipity minus more-like-this, paired on the same seeds, is +0.33 (0.32–0.34) in diversity and +0.001 (−0.007–0.008) in novelty. The serendipity list has greater measured diversity, with no clear difference in measured novelty.
Episode routes
Each transcript is cut into tenths, projected onto the fixed topic basis, and measured as a walk (sum of Hellinger steps). Intervals are 95% bootstraps over episodes; p-values are two-sided permutation tests on the difference of medians.
| Format | n | Median route | 95% interval |
|---|---|---|---|
| Solo lecture | 28 | 3.12 | 2.66–3.90 |
| Interview | 347 | 3.54 | 3.38–3.74 |
| AMA | 64 | 6.44 | 6.34–6.63 |
Solo minus interview is −0.42 (−0.90–+0.44), p = 0.22. AMA minus interview is +2.91 (2.66–3.16), p < 0.001. The interval does not establish a difference between solos and interviews. AMAs have longer routes under this measure.
Second representation
33,522 passages and 49,760 interview turns embedded with Qwen3-Embedding-0.6B. The Mantel correlation between the lexical and semantic episode geometries is 0.644 (p = 0.0005, 2,000 permutations); 46% of an episode’s ten nearest neighbours are shared between the two. In embedding space the three formats walk similar distances (medians 2.14, 2.19, 2.36; rank correlation with the lexical routes 0.04), so the apparent difference between formats depends on how the transcripts are represented.
Search by meaning
The Search page runs Heart of Gold’s relevance floor over 21,066 passages of about 376 tokens. The timing comparison below was measured on the original 20,842-passage snapshot. The reranker scores about 32 chunks a second, so the interactive budget was measured rather than picked, on twelve blind queries against the fully reranked floor.
| Rerank budget | Floor kept (28 chunks) | Top 10 kept | Wall time (median) |
|---|---|---|---|
| 4 s | 0.54 | 0.53 | 6.0 s |
| 6 s | 0.69 | 0.73 | 8.1 s |
| 8 s | 0.75 | 0.79 | 8.4 s |
| 12 s | 0.99 | 0.99 | 14.0 s |
The service runs at 12 s. The page shows the cosine-only floor after about a second and swaps in the reranked list when it arrives. When the machine is asleep the same box falls back to a BM25 keyword index over the same passages, and says so.
Stack
Python, scikit-learn, LightGBM, sentence-transformers, UMAP, matplotlib. A make-style DAG runner with fingerprinted stages. One HTML file plus a data file and lazily loaded charts, served from Cloudflare with a Worker route for search. The search service runs on a Mac under launchd through a Cloudflare tunnel, with a D1 FTS5 fallback.
My role
I built the Explorer around questions I had about the archive, including whether solo lectures move through subjects differently from interviews. I used both word-based topics and embeddings to check how much the findings depend on the representation.
Where this could be useful
The same kind of exploration could help a team browse a large interview archive or research collection. The topic labels and recommendations would need to be evaluated against the questions that team actually asks. These are potential applications of an independent project.
If you are hiring, the experience page says which business problem this project shares its mechanics with.